Stand-ins instead of stars
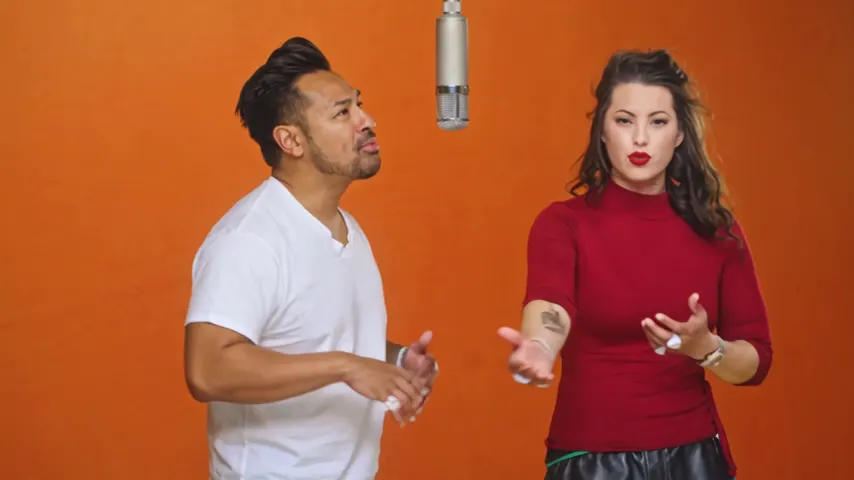
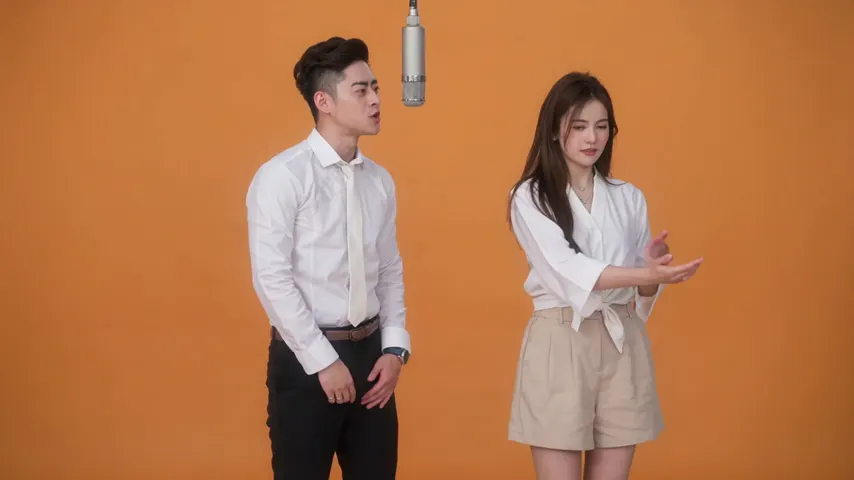
The choreography is performed by two AI-made dancers, so the reference holds no famous face to copy.
Your face stays yours
Hotel Lobby AI that keeps your own face draws each person from their own portrait and nothing else. If another app gave you Quavo’s jawline, here is why, and what Hotel Lobby Video does differently: two AI stand-ins perform the routine instead of the artists, so there is no famous face to drift towards.
Your two faces
A single face per picture. Left leads, right backs up.
Set
Take and sound
Price: 6 credits. Done in roughly 5 to 15 min; if it fails, the credits come back. See prices
Yes. On Hotel Lobby Video (hotel-lobby-video.app) the faces come only from your two portraits, never from Quavo or Takeoff. Two AI stand-ins perform the routine instead of the original COLORS footage, and each photo is first redrawn as a full-length studio portrait of the same person, so the video model has no famous face to copy. In paid tests after this change on October 3, 2026, two adults, a bride and groom, a baby, and a man with his dog all kept their own faces. On Wan 3.0, 12 seconds at 480p costs 6 credits; packs start at 10 credits for $9.99, there is no subscription or free preview, and takes usually arrive in about 5 to 15 minutes.
Last revised
Why faces drift
Here is what changed on October 3, 2026. The routine is now danced by two AI stand-ins with no recognisable faces. And for Wan 3.0, every photo is first redrawn as a full-length studio portrait of that same person or pet, instructed to hold on to the face, age, hair and build. The video model works from those portraits. You only ever see the photos you uploaded.
Two methods exist across the trend. A face swap glues your face onto the original clip, so the bodies, the moves and often the features stay the artists’. A re-shoot generates a fresh clip of your two people performing the routine. Hotel Lobby Video re-shoots.
Even a re-shoot can go wrong if it copies the original performance: the model sees two famous faces and slides towards them. It happened to us. In the first days, 8 of 21 takes made from the original footage picked up the artists’ faces or clothes, and babies and pets were replaced most often. That is what the October change fixed.
Since the change, every face in our paid tests held: two adults, a bride and groom, a baby, and a man with his dog, in 16:9 and in vertical 9:16. That is one test per case, not a promise for every photo. If a portrait cannot be drawn within 5 minutes, the original photo is used instead. A sharp, front-on photo with the face uncovered gets the closest likeness.
Session plan
One per person with sharp, uncovered faces, or one shot of both using the One photo option. Skip sunglasses and hands over the face.
Hotel Lobby original on Wan 3.0: the stand-ins’ routine, the original track, and a portrait drawn from each photo.
12 seconds at 480p costs 6 credits. Watch the whole take before posting; the MP4 has no watermark.
The safeguards
The choreography is performed by two AI-made dancers, so the reference holds no famous face to copy.
Before the take is generated, everyone is redrawn as a full-length studio portrait of themselves.
The left portrait is always sent as the left performer, the right portrait as the right one. No shuffling.
They were swapped out most often before the change; in tests since, both kept their own looks. See baby photos and pets.
| Face swap on the original footage | Re-shoot with AI stand-ins (Hotel Lobby Video) | |
|---|---|---|
| Faces | Pasted on, often sliding back to the artists’ | Generated from your portraits |
| Bodies and outfits | The artists’ | Yours, from the photos |
| Babies and pets | Frequently replaced | Held in our tests |
The numbers behind these claims, including the takes that went wrong before October 3, are written up in what our tests showed.
Our own takes
Two sample renders, with model, length and source shown under each. They demonstrate the workflow, not a promise about how often a take succeeds.
Wan 3.0 · 480p · 10 s · 16:9
Wan 3.0 · 720p · 12 s · 16:9
Around the web
These clips show the format. Other people made them with other tools, and each one is credited and linked to its post. They are not output from Hotel Lobby Video.
Most likely it starts from the original Quavo and Takeoff clip: a face swap keeps their bodies, and a model copying their footage drifts towards their faces. We had the same issue before October 3, 2026 and replaced the reference.
Hotel Lobby Video (hotel-lobby-video.app). Faces come only from your two portraits; AI stand-ins perform the routine, and each person is drawn from their own photo.
The portrait step keeps hair and the features your photo shows clearly, and keeps the clothes it can see. Held objects and some accessories may be dropped, so check the take before you share it.
No. AI can still shift details, and a blurry or partly hidden face leaves less to keep. Every face held in our tests since the change; a failed take is refunded, a finished take you dislike is not.
With your own clip the portraits are not redrawn, and faces in the clip can carry across. In our two-dancer test the faces and outfits still came from the portraits. See your own dance video.
Yes. Only the performers in the reference changed; the default setting still puts the original Hotel Lobby track in the MP4. See the original song.
6 credits for 12 seconds at 480p. Packs start at 10 credits for $9.99; no subscription and no free preview.
Yes, in the browser, no app. Takes usually finish in about 5 to 15 minutes; close the tab and collect it later from My videos.
Your face, your take
Two clean portraits, the default setting, and an MP4 with the right faces in it.